AI Search Visibility
How To Turn AI Visibility Data Into a GEO Roadmap in 2026

 JoseGrowthatOmnia
 AndreiHead of GrowthatOmnia
TL;DR
ChatGPT cites fewer domains per answer than any other major AI engine, and that number is shrinking. Reliable visibility tracking requires a structured methodology that includes building representative prompt sets, normalizing run conditions, separating mentions from citations, and choosing metrics that reflect real competitive position rather than raw counts. The four-branch decision framework maps each tracking outcome to a specific action, from content creation to PR outreach, so teams can close gaps across AI systems instead of just reporting them.
If you approach ChatGPT rank tracking like keyword rank tracking, you’re setting yourself up for failure. ChatGPT answers don’t occupy stable positions like blue links on the search engine result pages (SERPs). The answers are generated text subject to change with every model update, prompt rephrasing, or geolocation.
Per Omnia’s proprietary data, ChatGPT also has the tightest citation budget of any major AI engine. It averages roughly four cited domains per answer, which makes sloppy or small-sample tracking especially misleading. You need a proper tracking setup that accounts for all the prompt variability.
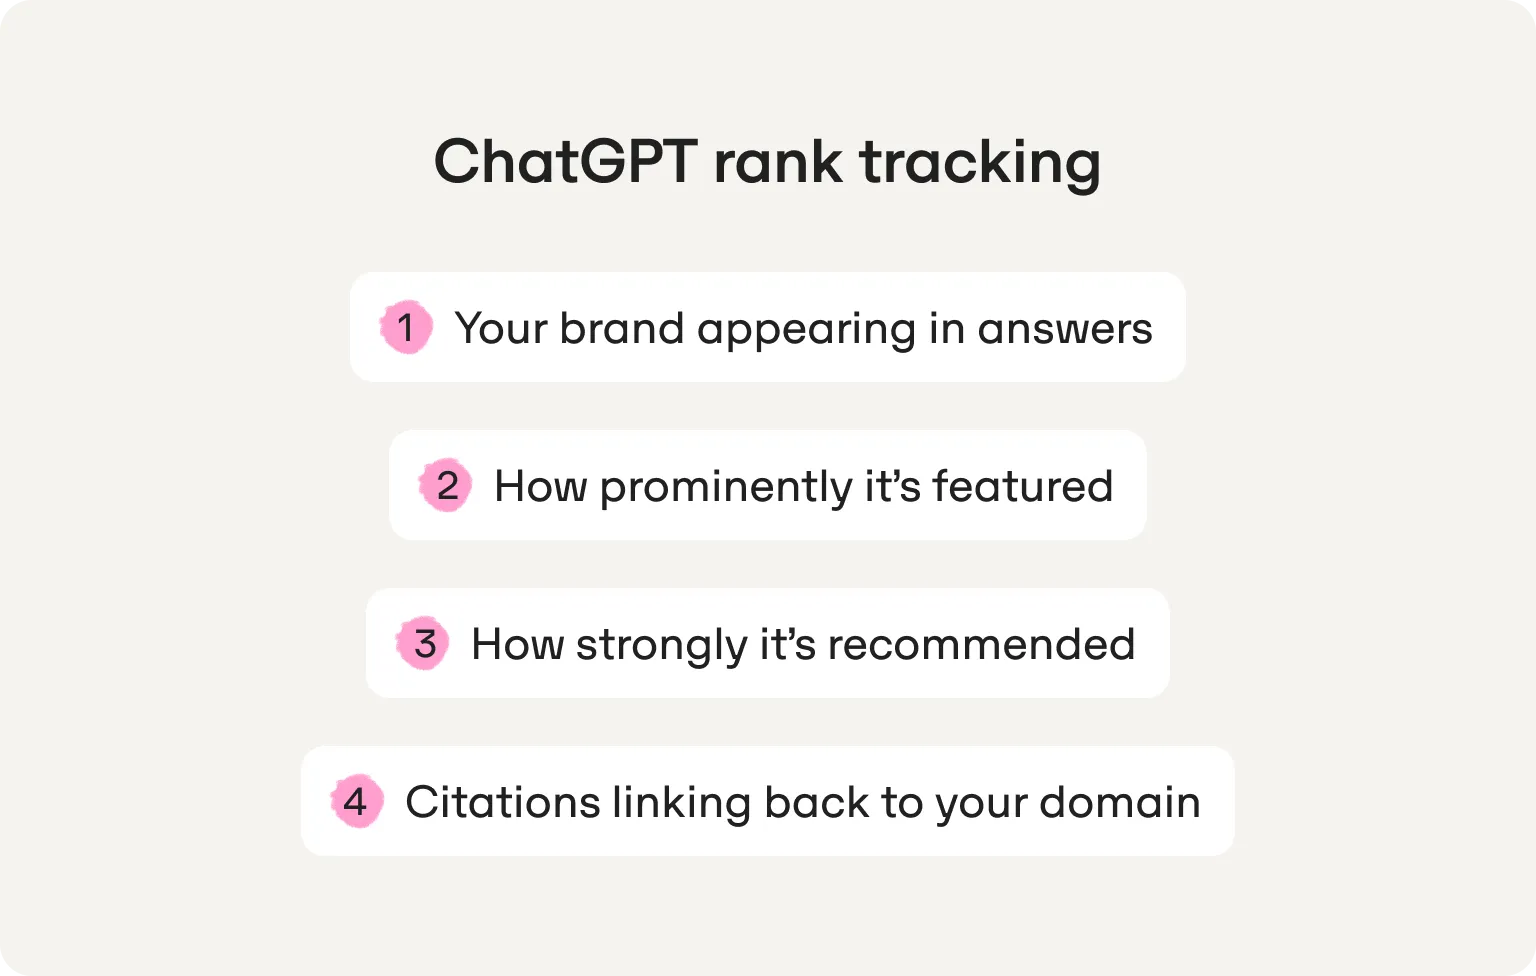
“Rank” in ChatGPT doesn’t mean position three on a search results page. It means prompt-based visibility, which is:
ChatGPT doesn’t expose numbered citation positions the way Perplexity does, so tracking has to measure presence and prominence instead of rank order. A brand that’s named first in a recommendation list and cited with a source URL is winning more than a brand that appears as a passing mention in the third paragraph. But neither of those outcomes maps to a stable numeric position.
This is fundamentally different from traditional search engines, where rank one means rank one. Because answers change over time as AI models update and the underlying web shifts, manual one-off checks are unreliable for any team that needs to track progress and monitor visibility volatility week over week.
ChatGPT cites roughly four domains per answer on average, based on Omnia's citation database of 42M+ tracked citations. That’s less than a third of what Google’s AI Mode cites (13.8 domains) and under half of what Perplexity cites (7.5 domains). The number has also been shrinking, not growing. ChatGPT’s average dropped from 5.1 domains per answer in September 2025 to 4.1 by April 2026. With so few citation slots available, a small or careless prompt sample will badly misrepresent your real brand visibility.
If you test 10 prompts and your brand appears in two of them, you might conclude you have 20% coverage. Run those same 10 prompts a week later and you could see zero, or four. The tight citation budget means the margin for sampling error is unforgiving, and the competitive dynamic is severe. There are only about four seats at the table, and the room is getting smaller.
Automated systems replace the guesswork of manual testing with reproducible, timestamped outputs. Any credible AI search monitoring tool follows the same basic pipeline:
Stored outputs, mention detection, citation URLs and domains, prompt IDs, and timestamps are reproducible. Sentiment analysis scoring, inferred narrative position, and intent classification are directional. Directional signals are useful for context, but they’re not precise enough to stand on as proof of performance.
A prompt set that reflects real buyer intent needs to cover the full range of ways your customers research solutions in AI search engines. That means comparison queries (“X vs Y for [use case]”), “best of” queries, alternatives queries, use-case-specific queries, and pricing questions. Each prompt should map to a real conversational intent your buyers express. Every prompt record should include:
There’s also a layer below the final answer that most teams miss. When ChatGPT researches a question, it generates internal sub-queries, sometimes called fan-outs, before writing its response. Seer Interactive found that these sub-queries increasingly contain brand names directly rather than generic category terms.
When a fan-out includes a specific brand, the model has effectively decided that brand is synonymous with the topic. Showing up in those sub-queries is a stronger signal than being one of several sources cited in the final answer, because it means the model treats your brand as the default authority for that topic.
When ChatGPT talks about a category and your name is in the sub-queries, you have AI mentions at the deepest level of the model's reasoning. This means your prompt research should track fan-out visibility alongside final-answer visibility.
Reliable ChatGPT rank tracking depends on controlling the variables that can distort your results. Here are the variables you can control:
The reason cadence matters is that ChatGPT is more volatile than most teams assume. Based on Omnia’s tracking data, ChatGPT changes its top-cited domain for a given prompt more often week to week than Google’s AI Overviews does. Only 8.1% of ChatGPT answers keep the same top-cited domain week over week, compared to 18.5% for AI Overviews.
The same Seer Interactive research also notes that running the same prompt 30 times in ChatGPT 5.5 produced meaningfully different fan-out patterns across runs, reinforcing that one-off checks cannot be trusted.
A mention means your exact brand name, product name, or domain appears in the answer text. In a zero-click AI answer, a mention without a citation is often all you get. Misspellings, entity confusion (which is when your brand is confused with a similarly named competitor), and abbreviated names all count. But these need to be flagged separately so you do not overstate your real presence.
A citation means ChatGPT links to or names a specific URL or domain as a source. Citations matter more than mentions as a lever for change because they tell you exactly which page or domain the model is drawing from, which means you can study it, replicate it, or compete with it. This is where authority building starts. You can’t earn a citation and then conduct proper media outreach if you don’t know which domains the AI model already trusts.
ChatGPT’s citation sources also skew editorial and encyclopedic rather than video-heavy, unlike Google's AI search engines. Wikipedia is the single most cited domain in ChatGPT with over 200,000 citations in Omnia's database, roughly 40 times more than it receives in AI Overviews. Zero social platforms appear in ChatGPT's top ten cited domains. This means that a strong ChatGPT citation is usually authoritative content published on editorial and reference sites, not video content or social posts.
The key metrics for tracking brand visibility in ChatGPT are:
Two advanced metrics are worth adding as your tracking matures. Brand fan-out visibility rate measures whether your brand appears in ChatGPT's generated sub-queries before the final answer is written. Brand co-citation tracks which other brands or sources consistently appear alongside yours, revealing competitive adjacency patterns that simple mention counts miss. Together, these metrics give you the trend analysis and historical trends you need to spot shifts before they become problems.
Raw mention count alone is misleading. ChatGPT's tight citation budget means a low absolute count does not necessarily mean poor performance relative to competitors. If your brand is cited in two out of four available slots, that's a strong position even though the raw number looks small.
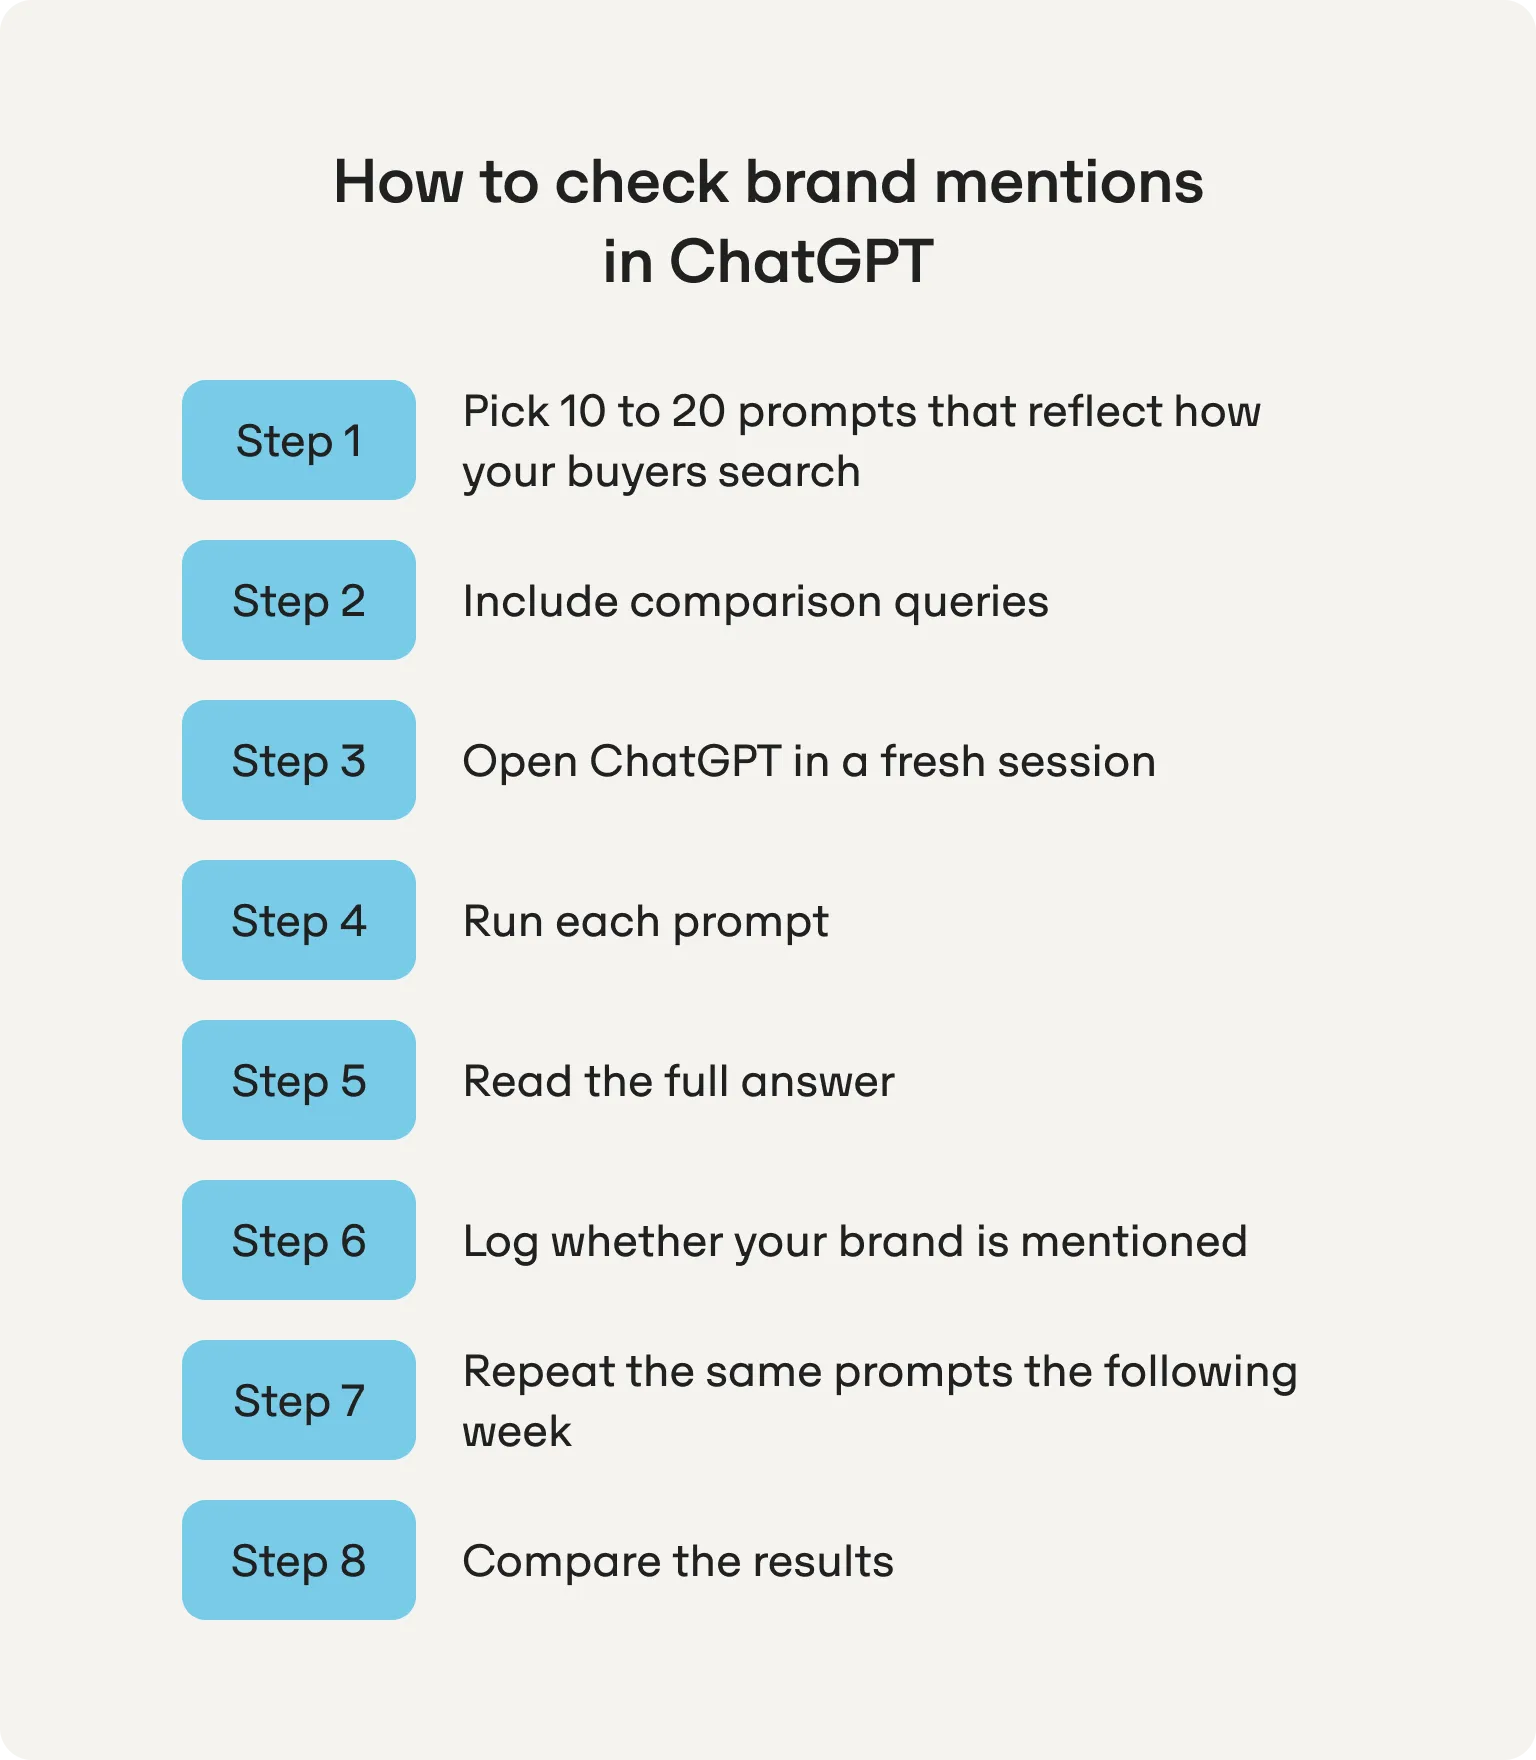
If you want to check brand mentions in ChatGPT today without a tool, here’s a process you can use:
This works for a quick baseline, but it breaks fast. Manual tracking introduces inconsistency between runs because you can’t perfectly replicate the session state, model version, or search context. There are no country controls either, so you can’t see how ChatGPT visibility varies across markets.
There’s no history to compare against beyond what you remember or scribble down. There’s no citation-level analysis, so you cannot see which domains are powering competitor wins. And there’s no competitor share of voice, so you can’t tell whether you’re gaining ground or losing ground relative to the brands you care about. You also can’t track competitors or run competitor monitoring at any real scale.
The next step up is a spreadsheet. Make a tab for your prompt list, a tab for each week’s results, columns for mention, citation, and competitor presence. This is a reasonable stepping stone for a team that is just getting started with answer engine optimization. But as you start to scale, it’s going to be hard to maintain.
Spreadsheets are fragile, hard to QA, and impossible to govern as the prompt set grows. They also can’t capture fan-out data, normalize for model version changes, or surface actionable insights about why competitors are winning. For remote teams especially, a shared spreadsheet with no version control and no audit trail is a liability.
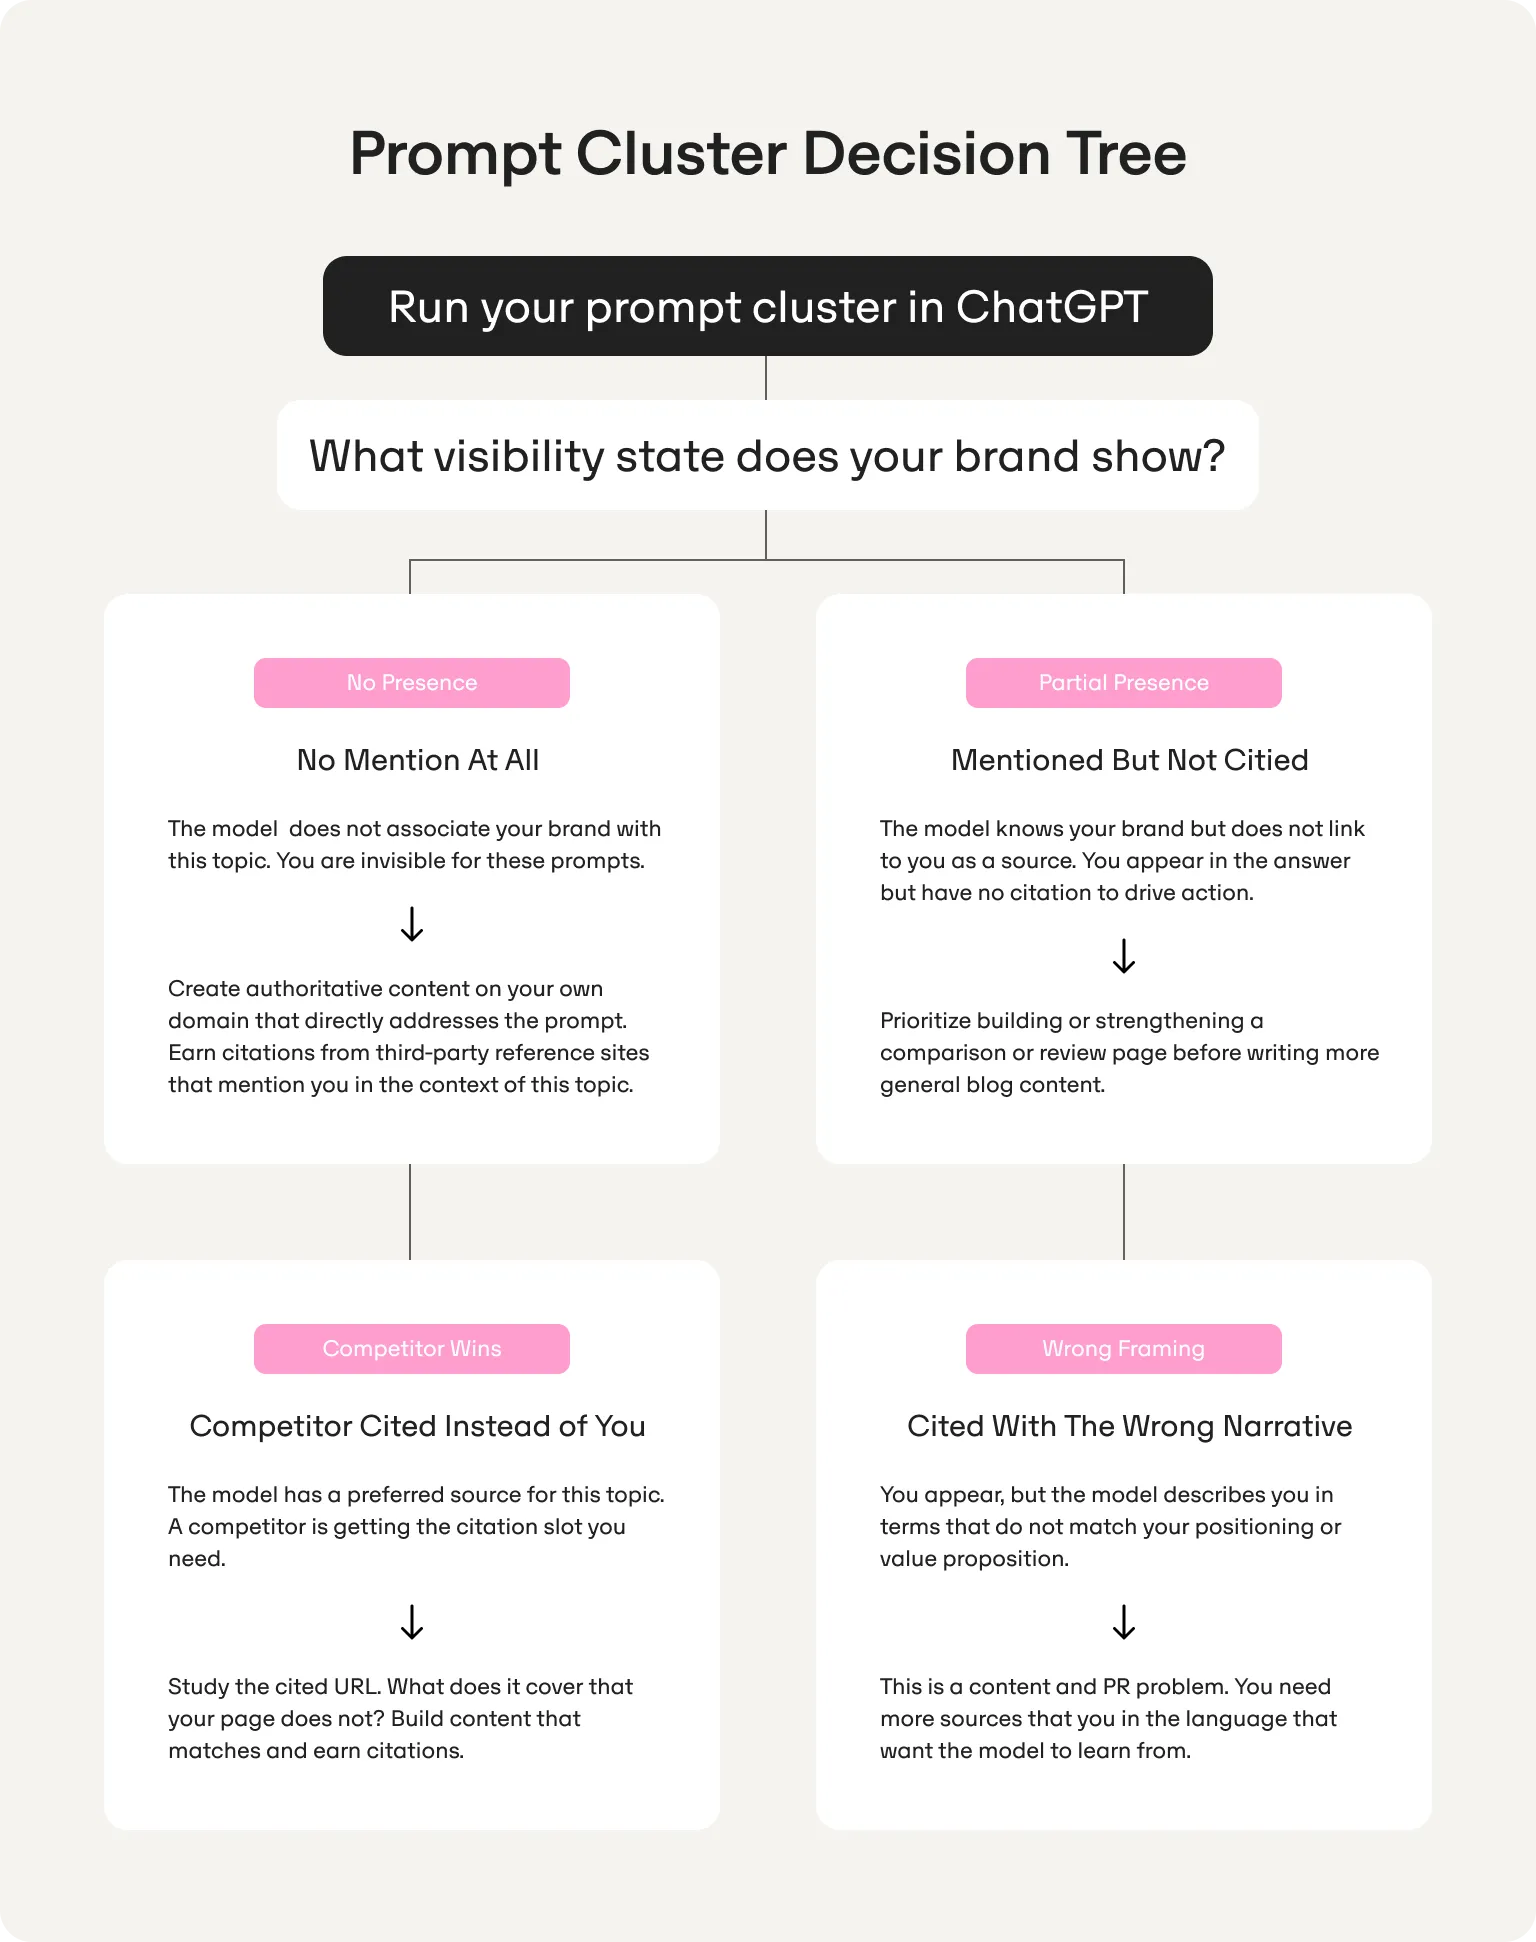
Data without a decision framework is just a dashboard. The goal is to go from raw outputs to concrete next steps: identify the prompt clusters where competitors win, find the citation domains powering those wins, compare your own site's coverage against them, and decide what to create or fix and where to place it. This is how you turn monitoring mentions into con
tent gaps you can actually close.
Use this decision tree for every prompt cluster you track:
Attribution from ChatGPT is imperfect. A clean referrer from “chat.openai.com” usually isn’t available in your analytics, so you can’t always draw a straight line from a ChatGPT mention to a demo request. Instead, build a “good enough” model that correlates AI visibility KPIs with assisted outcomes. Monitor referral sources where visible and add UTMs to any links you control that might appear in ChatGPT citations.
Watch for branded search lift in Google Search Console data. If your inclusion rate in ChatGPT increases, you should see a corresponding lift in branded search volume within a few weeks. Correlate AI visibility changes with demo requests, signups, or pipeline movement. You won’t get perfect attribution, but you will get enough signal to know whether your AI visibility work is driving real business outcomes.
If you’re a marketing or brand team at a startup or scale-up, your team needs more than a snapshot. You need a standing, country-by-country view of whether ChatGPT recommends your brand and whether that position is improving week over week. You don’t have time to babysit a spreadsheet, and you need measurable progress that you can show leadership without a six-month runway.
Omnia gives you country-level tracking across seven major AI search engines, citation intelligence at the URL and domain level, competitive share of voice, and an action layer that produces execution-ready output. It gives you recommendations, content briefs, outlines, and workflows. That action layer is what separates Omnia from other AI search visibility platforms that just give you dashboards.
Omnia’s Prompt Discovery surfaces the AI-native search prompts your buyers are actually asking, ranked by volume and difficulty across any country and language, and clustered by topic so you can prioritize the prompts where you have the best shot at winning. The Omnia MCP connector lets you connect your AI search visibility data directly to the AI assistants your team already uses, like Claude Desktop, Cursor, and Windsurf. Plus, pricing is transparent and every plan includes all seven engines and unlimited countries and languages, so you’re not penalized for tracking across markets.
Tracking multiple engines matters because ChatGPT is not a smaller version of Google. Google’s AI Mode and AI Overviews share 81.5% of their top-cited domains and behave like siblings, but ChatGPT overlaps with Google's engines only about half the time (52% with AI Overviews, 55.5% with AI Mode). Ranking well in AI Overviews does not mean you’re covered in ChatGPT. The two engines draw from fundamentally different source pools, and they reward fundamentally different content strategies.
Book a demo to see how Omnia surfaces your ChatGPT AI mentions, citation share, and competitive share of voice, or check pricing for your team. Start for free and track ChatGPT alongside all seven AI engines today.
Omnia offers a 14-day free trial on the Growth plan.
No credit card required. See exactly where your brand shows up (or doesn't) across AI engines, then let the platform's recommendations guide your next move.

Most brands new to tracking brand visibility find they appear in 10-30% of their relevant queries. A strong early target is appearing in over half your tracked prompts with at least some citations. Historical data shows whether mention frequency is trending up or down, not a single snapshot.
Configure your automated monitoring to capture exact brand name, product name, domain, and common misspellings separately. Flag entity confusion where ChatGPT AI responses mix your brand up with a similarly named competitor, so you don’t overstate your real brand's presence.
Tracking brand mentions in ChatGPT tells you whether your brand shows in the answer text. Brand monitoring goes further. It measures whether you are cited as a source, how prominently you are featured, and your competitive intelligence relative to competitor brands. Presence tracking is what marketing teams actually need to identify opportunities and close AI visibility gaps.
You need a platform that runs prompts from real browser sessions in target countries, not VPN approximations. Omnia supports country-level ChatGPT brand visibility tracking across all plans, so you can see how ai generated answers vary by market and language without upgrading to an enterprise tier.
The two AI platforms have fundamentally different citation fingerprints. Google AI overviews and AI Mode share over 80% of their top-cited domains, but ChatGPT overlaps with Google only about half the time. ChatGPT favors authoritative sites like Wikipedia and Forbes, while Google leans heavily on YouTube and social media channels. Winning in one engine doesn’t transfer to the other. You need a separate answer engine optimization strategy for each.
Written By
 AndreiHead of GrowthatOmniaJoseGrowthatOmnia
 Miguel FernándezCTO & FounderatOmnia
 JoseGrowthatOmnia
 The Omnia Team
 The Omnia Team
No credit card required · Free for 14 days · See your AI visibility within 3 minutes