AI Search Visibility
How To Turn AI Visibility Data Into a GEO Roadmap in 2026

 JoseGrowthatOmnia
 AndreiHead of GrowthatOmnia
TL;DR
Most GEO advice treats visibility as one problem with one checklist. It's actually four different trust hierarchies running in parallel. AI Mode and AI Overviews reward video and social discussion, ChatGPT rewards encyclopedic and editorial coverage, and a domain can dominate one engine while staying functionally invisible on another. The strategy isn't picking tactics off a list. It's knowing which public surfaces each engine actually trusts, and getting discussed on the right ones before you optimize anything else.
YouTube shows up +445,000 times in Google's AI Mode citations. On ChatGPT, the same domain shows up 16,000 times, a 28x gap on identical content, based on Omnia's tracking across 42 million citations. Wikipedia runs the opposite direction: 200,000 citations in ChatGPT against 5,000 in AI Overviews. These aren't close competitors pulling from a shared pool of trusted sources. AI Mode and AI Overviews share 81.5% of their top-cited domains, they're built from the same ecosystem. ChatGPT overlaps with either one at barely half that rate, and its top 10 sources contain zero social platforms.
That gap is the actual starting point for a generative engine optimization strategy, not a footnote to one. Most GEO advice hands you a single tactic list and treats every engine as one target. But if AI Mode and ChatGPT trust almost entirely different sources, a strategy built for one is, at best, doing nothing for the other, and at worst, mistaking presence on one engine for coverage you don't actually have. A real GEO strategy has to start by mapping which engines your buyers actually use and which public surfaces those specific engines pull from, before a single piece of content gets built or a single tactic gets picked off the usual list.
That's what the rest of this guide is built to do: not another list of best practices, but a way to diagnose where you're actually missing, on which engine, and what closes that specific gap.
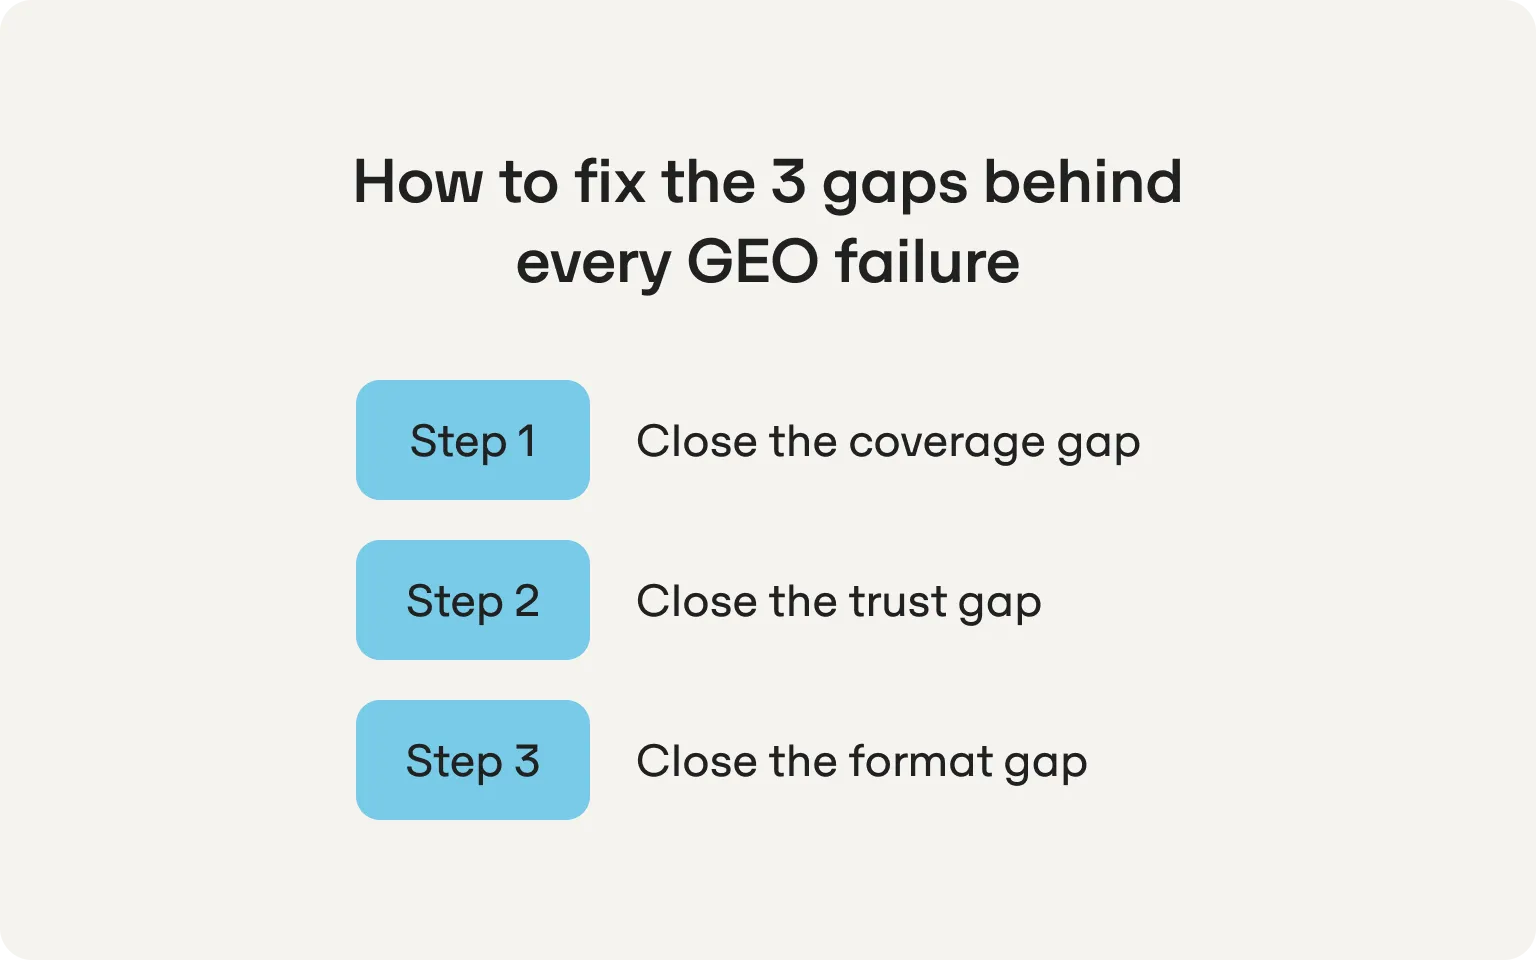
Most brands don't have a GEO problem. They have one of three distinct problems, and running the same tactic list against all three is exactly why nothing moves.
| Gap | What it looks like | What actually fixes it |
|---|---|---|
| Coverage gap | You're absent from AI answers for prompts you should win | Map the real prompts your buyers ask per engine, then publish to the surfaces that engine actually pulls from |
| Trust gap | You appear, but a competitor gets named or cited instead of you | Get discussed on the specific surface each engine already trusts, video and social for Google's engines, editorial and encyclopedic coverage for ChatGPT |
| Format gap | Your content or data exists, but nothing about it is structured to be lifted as a direct answer | Package it as a benchmark or comparison with a clear method, a stated result, and a stable URL |
These aren't three equally-weighted categories to work through in any sequence. Coverage comes first because you can't diagnose a trust or format problem on a prompt where you don't show up at all. Fix coverage before you touch anything else, or you'll spend a quarter perfecting a page's structure for a conversation your brand was never invited to.
You can't be trusted or cited in a conversation you're not part of, and how many conversations are even available to you depends entirely on which engine you're asking about.
Based on Omnia's tracking across 42 million citations, the number of domains an engine cites per answer varies by more than 3x:
| Engine | Avg domains cited per answer | What that means for coverage |
|---|---|---|
| Google AI Mode | 13.8 | The most open field, expanding 27% over five months |
| Google AI Overviews | 9.2 | Roughly 9 slots per answer, stable since late 2025 |
| Perplexity | 7.5 | Tightening, down from a peak of 11.8 |
| ChatGPT | 4.1 | Only 4 seats, and still shrinking |
Getting cited by ChatGPT is roughly 3x harder than getting cited by AI Mode simply because there are 3x fewer seats at the table. That's not a content-quality problem. It's a scarcity problem, and it changes how much effort a coverage push on ChatGPT is worth relative to the same push on AI Mode.
The tactic itself is simple to state and consistently skipped: translate what you'd normally target as a keyword into the actual prompt a buyer would type into each engine, since the same intent produces different language depending on where it's asked.
| Starting keyword | Google AI Mode prompt | ChatGPT prompt |
|---|---|---|
| "AI visibility platform" | "best AI visibility tools compared" | "what's the best tool for tracking brand mentions across ChatGPT and Perplexity" |
| "GEO agency" | "top GEO agencies near me" | "which agencies actually understand generative engine optimization" |
Mapping the real prompts your buyers ask has to happen before anything gets built, not after a piece is already written and you're checking whether it happens to rank.
Given the scarcity gap above, prioritize in this order:
For a worked example of what closing a ChatGPT-specific coverage gap looks like end to end, see how to rank in ChatGPT search.
Appearing in an answer and being trusted enough to get named directly inside it are two different outcomes, and which surface earns that trust depends entirely on which engine is asking.
According to Omnia's citation data, each engine pulls its most-trusted domains from a different kind of surface entirely:
A brand built entirely on video content can look dominant in AI Mode and be nearly invisible in ChatGPT. A brand with strong editorial press coverage sees the opposite. Neither is a content-quality failure. It's a mismatch between where the brand is discussed and what the specific engine already trusts.
Seer Interactive's research on ChatGPT 5.5's fan-out behavior shows the sharpest version of this. When someone asks a broad question, the model doesn't just answer directly, it silently runs a set of narrower sub-queries first, then builds the answer from what those sub-queries return. Seer found those sub-queries increasingly contain brand or individual names instead of generic category terms:
Running one prompt 30 times, Seer found named individuals appearing in roughly half the resulting fan-outs, while brands that used to win the old, generic version of that sub-query were frozen out entirely.
This is the part worth sitting with: Seer's diagnostic for why a brand gets pulled into a fan-out isn't about on-site content at all. It's whether the brand is being discussed on human, off-platform channels, LinkedIn posts, conference talks, trade press, Slack and community mentions, versus purely algorithmic traffic sources. Publishing more on your own domain doesn't create this signal. Being talked about elsewhere does.
Practically, that means:
Original data earns citations. Publishing a number by itself usually doesn't.
Research from Kevin Indig and Amanda Johnson at Growth Memo, built on Gauge's citation data across 301 cited pages and 1,075 citations, found that primary research, pages where the underlying data and methodology actually live, made up only 2.7% of what got cited. But those pages pulled in 8.4% of total citation volume. Primary research averaged 11.3 citations per page against 3.4 for everything else, a page that owns its data earns roughly 3.3 times the citation density of one that doesn't.
That advantage concentrated almost entirely in benchmark-format pages, ones that name and measure specific options against each other and publish a direct comparison result. Topics without a clean "which is best" question produced almost no cited primary research, regardless of how much original data existed behind them.
The myth worth killing here: owning proprietary data isn't the asset. A benchmark built from it, one that leads with the result and stays put, is what an AI engine can actually find and lift.
A framework tells you what to fix. It doesn't tell you what to do on a Monday. This is the part that does.
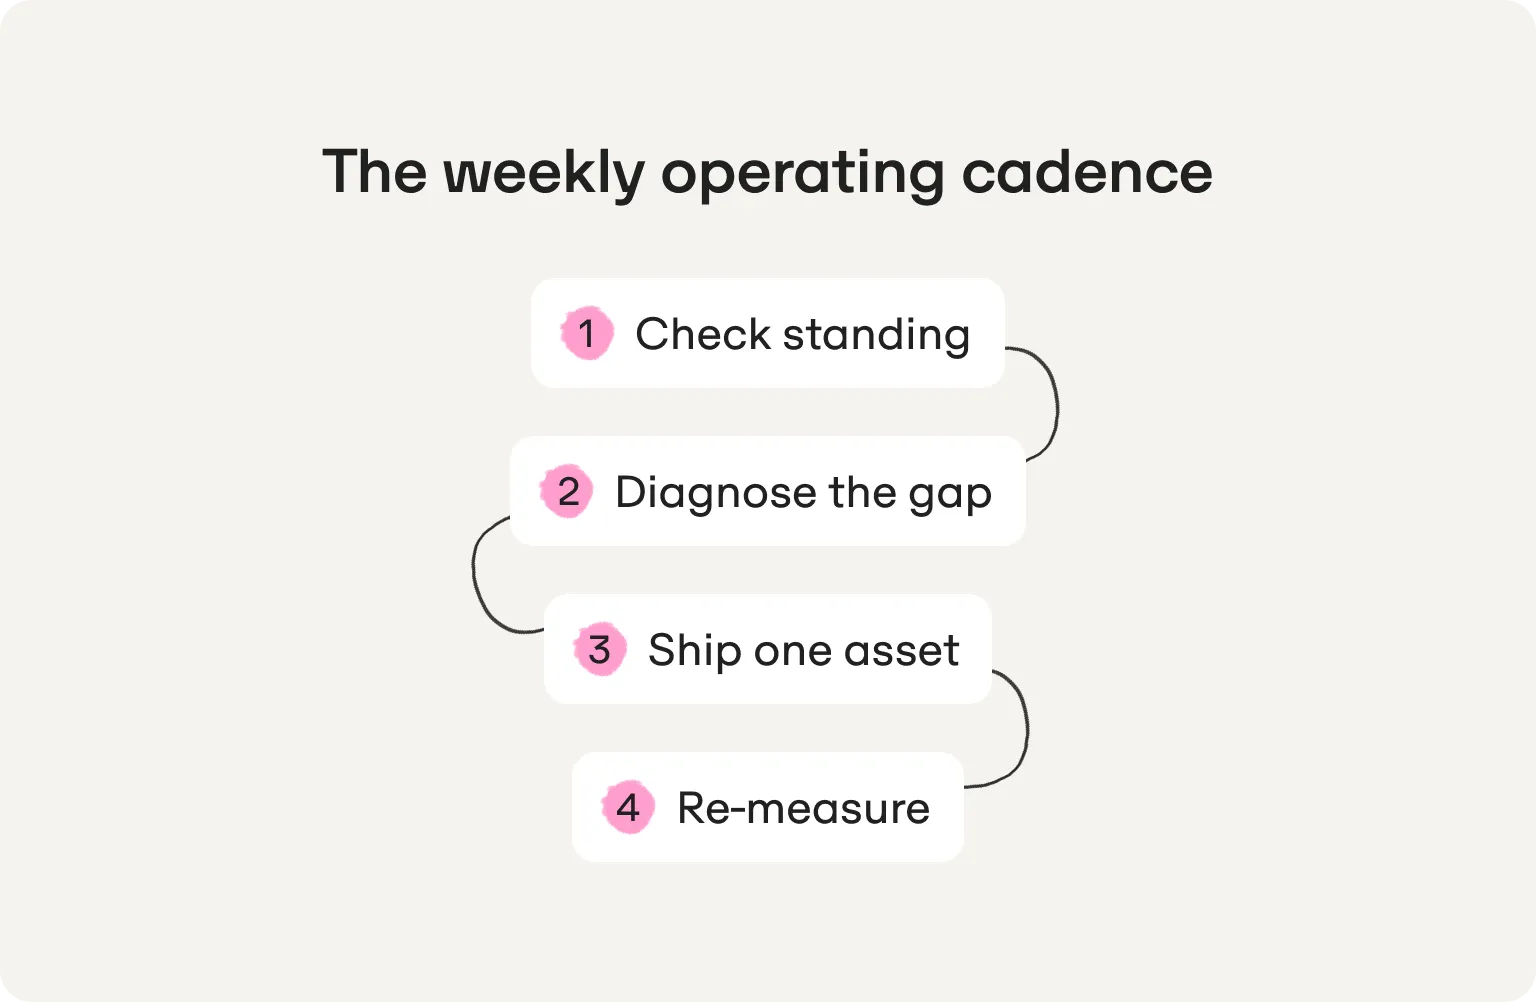
GEO isn't a project with an end date, it's a cadence you run every week:
The order matters as much as the steps themselves. Shipping before diagnosing is how teams end up publishing content that fixes a gap they don't actually have.
| Week | Focus |
|---|---|
| 1 | Baseline your standing across all mapped prompts and engines, then diagnose |
| 2 | Ship against the biggest coverage gap, likely on the engine with the fewest seats you're missing |
| 3 | Ship against a trust or format gap surfaced in week 1 |
| 4 | Re-measure everything, then decide whether week 5 repeats the same gap type or moves to a new one |
Four weeks isn't a finish line. It's one full pass through the loop, and the loop repeats indefinitely, since citation share shifts week to week, not once a quarter.
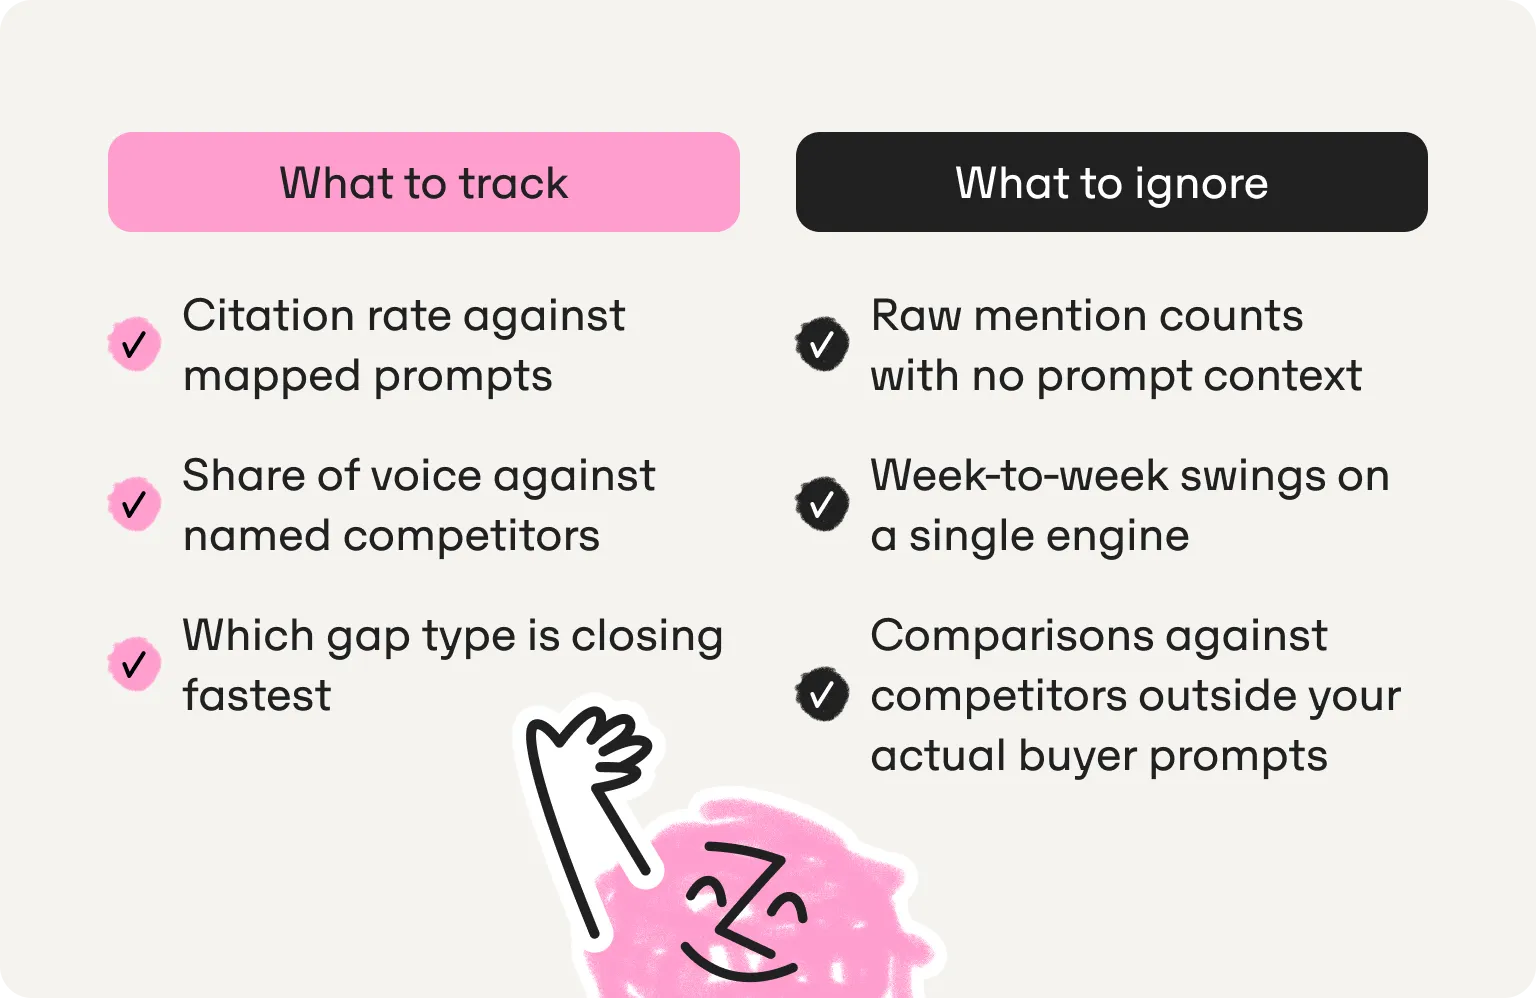
Running this loop by hand, four engines, a full prompt map, a fresh diagnosis every week, is the part that breaks down in practice. Most teams manage the first cycle, then the cadence quietly stops.
Omnia tracks citation status across all seven engines it monitors using API access and real-browser simulation, so the weekly check in step one isn't a manual pull across four separate tools. It surfaces which gap type is active for each missed prompt, then turns that diagnosis into the content brief and draft needed for step three, closing the loop between finding the gap and shipping against it instead of leaving that translation to whoever has time that week.
If you haven't mapped your current standing yet, run a free AI ranking check to get your week-1 baseline. If you're ready to keep the loop running instead of rebuilding the diagnosis by hand every week, here's how to monitor AI search visibility as an ongoing system.
Omnia offers a 14-day free trial on the Growth plan.
No credit card required. See exactly where your brand shows up (or doesn't) across AI engines, then let the platform's recommendations guide your next move.

There isn't a single best strategy, because there isn't a single engine. The strategy that wins ChatGPT, editorial and encyclopedic coverage, is close to irrelevant on AI Mode, which rewards video and social discussion instead. Start by mapping which engines your buyers actually use, then diagnose your gap on each one separately.
Largely yes. AI Mode and AI Overviews share 81.5% of their top-cited domains and behave almost like one engine. ChatGPT overlaps with either at roughly half that rate and pulls from a different kind of source entirely. Treating all engines as one target is the most common reason GEO effort stalls.
It depends on which gap you're closing and which engine you're targeting. Coverage gaps on an expanding engine like AI Mode can close within weeks. ChatGPT is more selective by design, with only around four citation seats per answer, so closing a coverage gap there takes longer and is worth more once it happens.
It depends on team size more than function. The work draws on SEO fundamentals but adds prompt mapping and cross-engine tracking that traditional SEO tooling doesn't cover. What matters more than reporting lines is that someone owns the weekly cadence, since GEO work that only happens during quarterly planning falls behind within a month.
Weekly, not quarterly. Citation share moves on a weekly timescale, ChatGPT alone changes its top-cited domain 92% of the time week over week, so a quarterly review is already looking at stale data by the time it happens.
Written By
 AndreiHead of GrowthatOmniaJoseGrowthatOmnia
 Miguel FernándezCTO & FounderatOmnia
 JoseGrowthatOmnia
 The Omnia Team
 The Omnia Team
No credit card required · Free for 14 days · See your AI visibility within 3 minutes